
A document assistant can quote a real page number and still give the wrong answer. The number may have lost its decimal point during OCR. A table value may have drifted into the neighboring column. A scanned exception may never have reached the model because an extractor found a digital header and assumed that the page already contained usable text. These failures happen before the first DeepSeek request, and a more elaborate prompt cannot reliably reconstruct the missing evidence.
A dependable DeepSeek document-processing workflow therefore starts with the document, not the chat window. It preserves the original, decides how to handle each page, checks the extracted evidence, and carries source identifiers through every transformation. Only then does it ask a model to interpret a bounded selection. The aim is not to turn every PDF into one long string. It is to make each important claim traceable to the right part of the right source.
This guide builds that workflow around a small, reproducible local experiment. We generated a fictional three-page dispatch handbook, extracted its digital pages, recognized its scanned page, and checked the resulting page records and chunks. No private document was used, and no paid or live DeepSeek API request was made. The local results demonstrate extraction and provenance mechanics; they do not measure DeepSeek answer quality, production OCR accuracy, or the safety of accepting arbitrary uploads.
Capability check: The product details below were checked against official documentation on October 3, 2026. Model names and accepted inputs can change, so treat the dated capability boundary as part of your integration configuration.
1. Separate the PDF, the parser, and the model input
The current hosted API should not be described as universally text-only. DeepSeek documents image input for deepseek-flash, currently served by DeepSeek-V4.1-Flash. Its model table does not list vision support for deepseek-v4-pro. The documented Files API accepts JPEG, PNG, GIF, and WebP images. Native PDF upload is not documented for that route. A request field named file is not a promise that every file format is supported.
There are consequently two useful application routes. In the text route, your application extracts and verifies text before placing it in a model message. In the visual route, it renders selected PDF pages or crops into a supported image format and sends them to a vision-capable model. The second route can retain visual context that plain text loses, but it also introduces rendering choices, image sizing, and another opportunity for small characters to become unclear. Neither route removes the need to check evidence.
Do not infer the developer API contract from an upload button in a consumer app. An app may perform its own parsing before the model sees anything, and its interface does not define an API payload. Similarly, the official DeepSeek-OCR and DeepSeek-OCR-2 repositories describe separately operated inference workflows. They are possible parser candidates, not evidence that an identically named model can be called through the hosted chat API. Choose and test the actual interface your application will use.
For ordinary prose questions, a verified text representation is often simpler to inspect, minimize, and cite. For a diagram, a crowded table, or a layout-dependent question, selected images may be necessary. Keep that decision explicit in a capability-aware route rather than silently sending the same payload to every model. Our DeepSeek model-routing guide covers the downstream selection policy; this article concentrates on producing evidence that any eligible route can use responsibly.
2. Preserve the source and inspect every page
Start by assigning the received document an immutable identity. A content hash helps distinguish two files with the same display name and reveals whether a later revision contains different bytes. Keep the original file separate from derived images, searchable copies, transcripts, and chunks. A hash supports identity and integrity checks; it does not authenticate the author or establish that the document’s contents are true. Those are separate trust questions.
Create a page manifest before extraction. Record the physical page count and a status for each page, including blanks and failures. A pipeline that returns only successful text blocks can look healthy while silently omitting the most important page. The manifest gives you a denominator: every original page must be represented by usable evidence, an intentional exclusion with a reason, or an unresolved review state. A timeout is not the same thing as a blank page.
Distinguish the zero-based index used by a library from a one-based physical page number used in a viewer. Also preserve a PDF page label when available, and record a visibly printed page number separately if the task requires it. Front matter might use Roman numerals; an appendix might restart numbering. A citation such as “page 7” is ambiguous unless the interface tells the reader which numbering system it means. The small example below uses one-based physical pages throughout.
Intake is also a resource boundary. Limit file bytes, pages, work duration, and memory, and isolate parsers from unnecessary network and filesystem access. A small compressed PDF can expand into expensive content streams, so an upload-size check alone does not provide a security guarantee. The teaching script has modest byte and page limits and subprocess timeouts. It does not implement the operating-system sandbox, memory enforcement, malware handling, or authorization controls required by a public upload service.
3. Route OCR carefully, especially on mixed pages
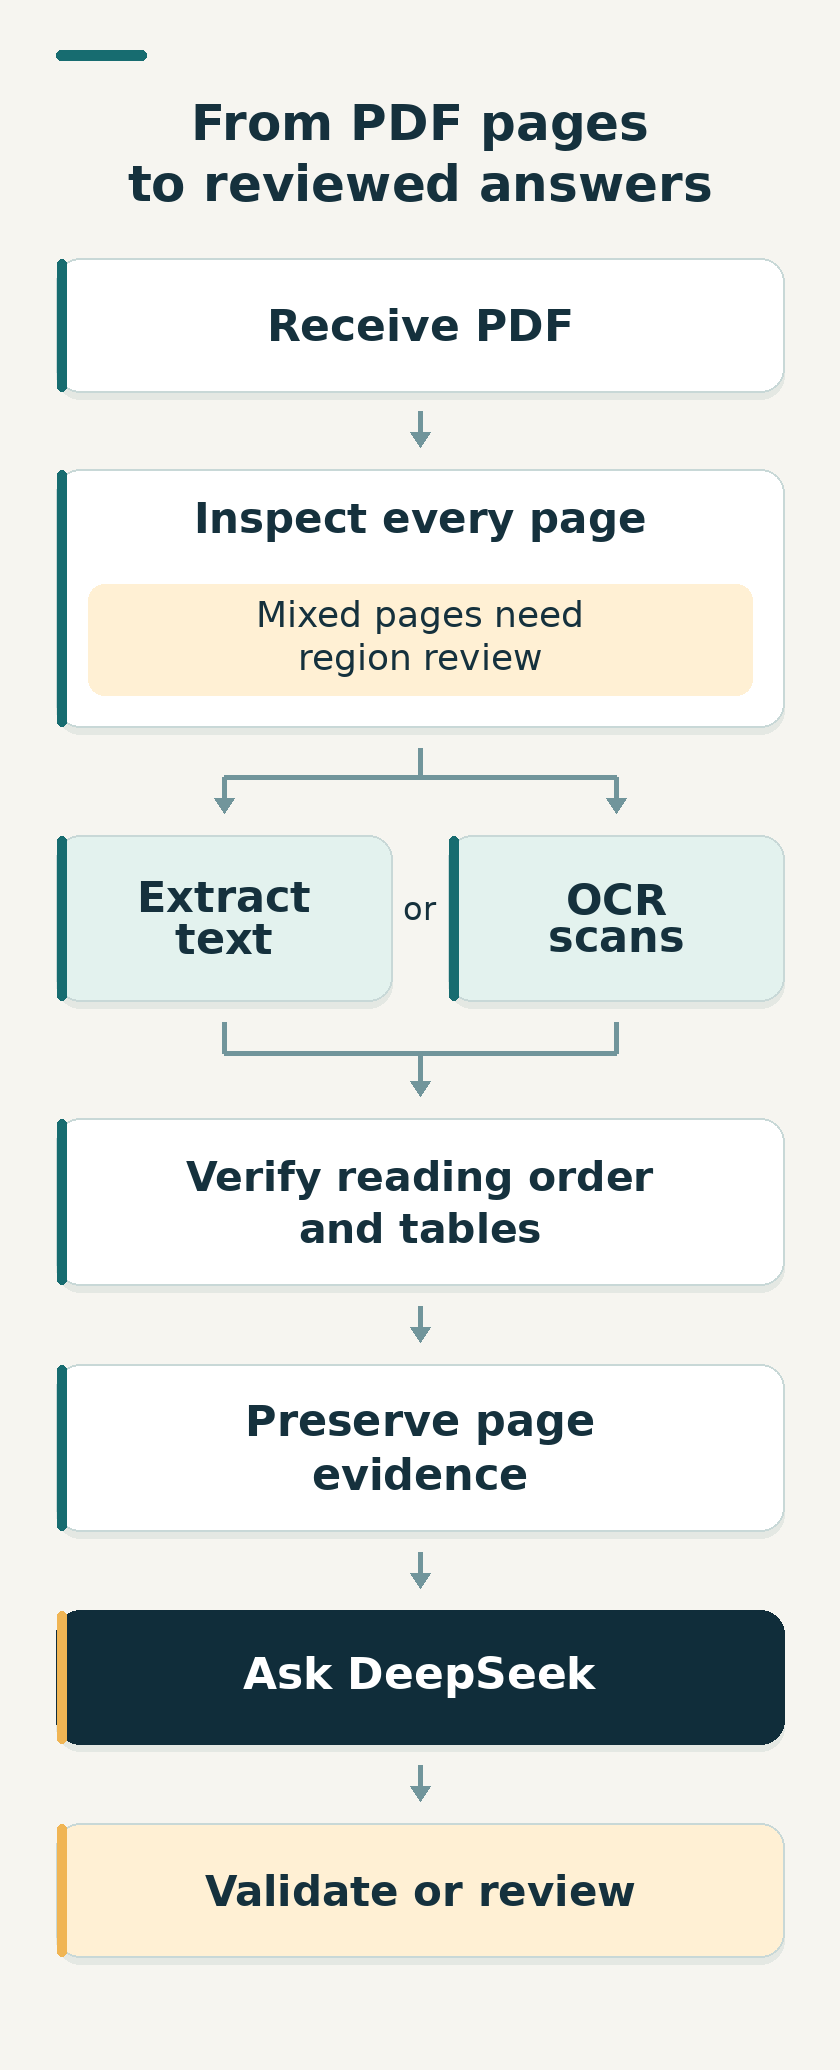
A born-digital page may contain text that a PDF library can extract directly. An image-only scan has no equivalent native text layer, so ordinary extraction can return nothing. A third case contains an existing OCR layer, which may be inaccurate even though selecting text appears to work. A fourth mixes native text and scanned regions. These are page-level and sometimes region-level distinctions; calling the entire file “scanned” or “digital” can hide the difficult cases.
Empty or very sparse extracted text is a useful warning, but nonempty text is not proof of completeness. Imagine a page with a digital company name above a scanned schedule. An extractor can recover the company name while losing every appointment. A routing heuristic based only on character count might mark that page as successful. Use rendered-page inspection and layout-aware checks on the document families you actually receive, and retain a review flag when coverage remains uncertain.
OCRmyPDF illustrates why the processing mode matters. Its skip mode skips OCR and image processing on pages that already contain text; it does not simply skip the text regions and recognize everything else. A tiny digital header can therefore leave an image body untreated. Redo and force modes have different effects. Force rasterizes printable content and can flatten interactive objects, while reprocessing can affect a PDF’s structural information. Preserve the original and choose a mode deliberately rather than treating stronger-sounding flags as harmless improvements.
Another subtle trap is the sidecar text file. OCRmyPDF documents that its sidecar contains text generated by its OCR process, excluding pre-existing text and pages omitted for various reasons. Sending only that sidecar to a model can discard the digital half of a mixed document. If you use a searchable output PDF, extract and reconcile its pages against the original manifest. Verify completeness instead of assuming that a successful OCR command produced a complete transcript.
OCR language, orientation, page segmentation, and image quality should be versioned inputs. Tesseract recommends at least 300 dpi as general quality guidance, but resolution alone does not guarantee correct recognition. Our deliberately clean synthetic scan was tested at 180 dpi to exercise the local mechanism, not to recommend that setting for production. Handwriting, skew, compression, unusual fonts, and multilingual content require their own samples and review policies. Increasing resolution without checking the result can merely make a wrong answer more expensive.
4. Repair reading order before reasoning about meaning
A PDF often describes where characters appear rather than presenting a simple linear story. Tagged PDFs can carry structural information, but you cannot assume that every supplied file has useful tags or that every parser preserves them. Text extraction may follow creation order, which can differ from the order a person reads. A late-added footer can appear in the middle of the transcript; two columns can become alternating fragments.
Use geometry when layout matters. Word or block coordinates let an application separate columns, associate a caption with a figure, and preserve a footnote near the statement it qualifies. PyMuPDF offers positional extraction and a top-left-to-bottom-right sorting option. That sort is a useful tool, not a universal semantic reading-order solver. A sidebar, spanning heading, or irregular table may require region-specific handling and a human-checked rule for the relevant template.
Keep the raw extraction alongside a normalized representation. Whitespace cleanup is usually easier to justify than changing punctuation, numbers, or line-end hyphens. Removing every hyphen can turn a negative value into a positive one or damage a product code. Joining broken words may help retrieval while invalidating character offsets. If your interface highlights an exact source span, preserve a mapping from normalized text back to the original blocks instead of pretending that offsets survive arbitrary cleanup.
Headers and footers need similar restraint. Repeated page furniture can waste context, but an apparent footer might contain the revision date, confidentiality condition, or exception that changes the answer. Learn removal rules from representative files, retain removed material in the audit record, and test whether important facts disappear. A cleaner transcript is useful only when its omissions are intentional and defensible. Visual tidiness should never be the sole criterion for deleting evidence.
5. Treat a table as relationships, not a bag of numbers
A table’s meaning lives in the associations among row labels, column headers, units, values, and notes. Extracting “Standard, 20.0, Express, 12.0” is insufficient if the system loses whether those numbers are kilograms, dollars, or delivery days. A table parser can help recover cells, and PyMuPDF includes table-detection facilities, but merged headers, borderless layouts, and page continuations still require validation. A successful function return does not certify the business interpretation.
Represent a verified row with its relevant context. In our fictional handbook, “Express” belongs with “maximum mass per carton,” “12.0,” and “kg.” The distinction between a carton and an entire shipment matters as much as the number. If a row is converted into a sentence, keep those qualifiers rather than emitting a generic limit. Retain the table’s source page and, in a richer pipeline, its bounding box so a reviewer can inspect the original arrangement.
For a multi-page table, carry forward only headers that you have verified belong to the continuation. Preserve any changed unit, subtotal, or section boundary. Repeating the first page’s header over every later row can create a systematic error when an appendix switches from kilograms to pounds. When chunking rows, include the relevant header and notes in each chunk and record every contributing source span. Do not cite the first page for a value that actually appears three pages later.
Numerical validation should be targeted. Check decimal separators, minus signs, percentages, date formats, and units against the source. If a total is supposed to equal a sum, calculate it independently, but avoid inventing arithmetic relationships that the document never states. In the handbook example, the 20.0 kg standard-service limit and the 8.0 kg Saturday exception must not be added together. They are alternative constraints under different conditions, not components of a combined allowance.
6. Build evidence records that survive chunking
An evidence record should identify the source, its location, the extraction method, and the text actually obtained. For a production system, useful fields include document hash, physical page, PDF label, region coordinates, parser version, OCR configuration, raw text, normalized text, and review flags. Keep configuration details outside the model payload when they are not needed for the task, but make them available to diagnostics and reviewers. Traceability should not depend on whatever wording a model happens to return.
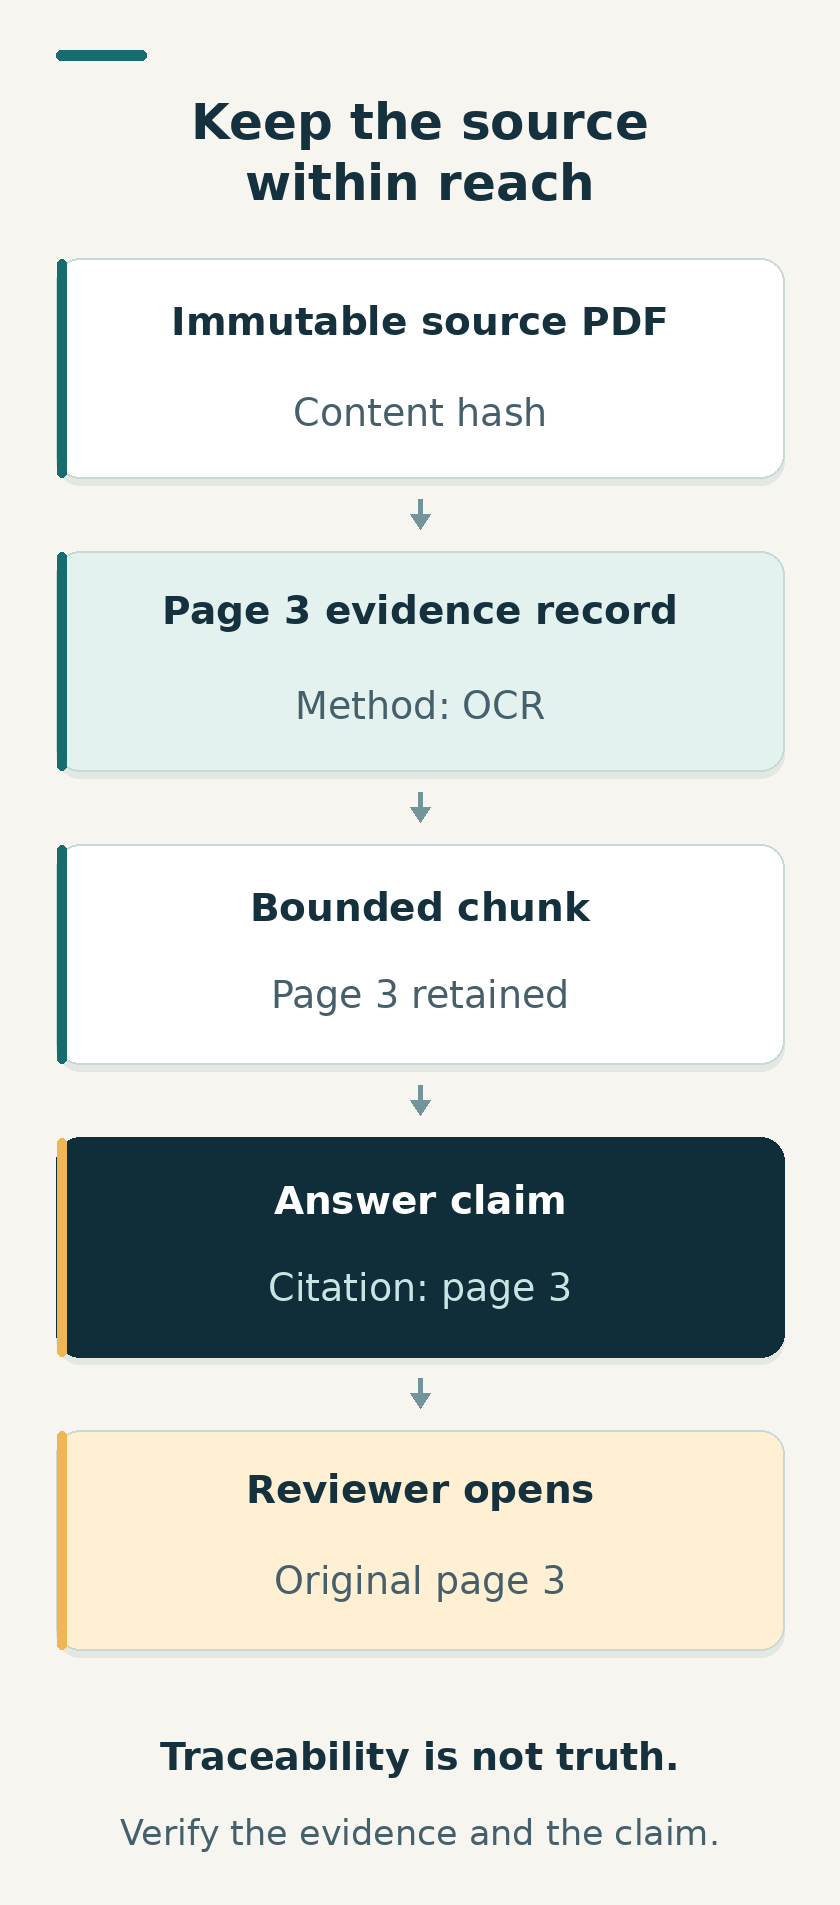
The local example uses a deliberately smaller contract: a document hash, one-based page number, extraction method, status, and page text. Chunk identifiers include that source identity and physical page. The code never joins material across pages, so a chunk cannot accidentally inherit one page number while containing text from another. This makes the demonstration easy to audit, although it is not a complete solution for paragraphs or tables that legitimately span pages.
Choose chunk boundaries according to the evidence, not only a nominal size. Keep a rule near its exception, a definition near its scope, and a table row near its header. A fixed character limit is useful for a transparent demonstration but can split a sentence in the middle of a qualifier. It is also not a token budget. Production code should use the tokenizer or estimation method appropriate to its model and reserve room for instructions, the question, and the answer.
Overlap is not automatically safer. It can preserve a sentence across boundaries, but it can also duplicate evidence, inflate apparent agreement, and complicate citation mapping. If you use overlap, preserve source offsets and deduplicate at the evidence level when counting coverage. If you merge pages, attach all contributing spans. The governing rule is simple: transformations may change the representation, but they must not silently change where a claim appears to come from.
7. Run a bounded local experiment before connecting a model
Our fixture contains three pages of fictional dispatch instructions. Page 1 is native text: business-day orders approved before 14:00 UTC target same-day dispatch, while approval at 14:00 or later targets the next business day. Page 2 is a native table with per-carton mass limits of 20.0 kg for Standard, 12.0 kg for Express, and 15.0 kg for Returns. Page 3 is a raster-only Saturday exception for lane N7, with a 10:00 UTC cutoff and an 8.0 kg per-carton limit.
The fixture was designed to expose one concrete omission, not to resemble a comprehensive benchmark. Ordinary text extraction recovered pages 1 and 2 and returned no text on page 3. With OCR enabled, the pipeline recovered the exception text and kept it attached to physical page 3. That observation is useful because an otherwise plausible answer based on the first two pages could miss the exception entirely. It does not establish performance on degraded scans, real operational documents, or arbitrary table layouts.
The script below uses pypdf for native extraction and invokes Poppler’s pdftoppm and Tesseract for an explicitly enabled OCR fallback. Install those tools and Tesseract’s English language data before using the OCR option. Run it only on trusted, bounded test documents while developing the workflow. It has no network calls and does not send a file or its contents to DeepSeek. Its output is the evidence envelope that an application can inspect before deciding what is appropriate to transmit.
The sparse-text rule is intentionally visible: fewer than 40 ASCII letters triggers a warning or OCR. That is a teaching heuristic, not a multilingual classifier or a completeness detector. A page in another script, a short cover sheet, and a page with a digital header can all defeat its assumptions. Every nonempty page remains marked for review. Replace this routing hint with evaluated page and region logic before relying on it for unfamiliar document families.
"""Local teaching pipeline for a trusted, bounded synthetic PDF.
Not a secure upload service or a general layout/table parser. No network calls.
Requires pypdf; OCR additionally requires pdftoppm and Tesseract with eng data.
"""
from __future__ import annotations
import argparse
import hashlib
import json
import re
import subprocess
import tempfile
from pathlib import Path
from pypdf import PdfReader

MAX_BYTES = 10 * 1024 * 1024
MAX_PAGES = 20

def normalize(text: str) -> str:
    """Keep line boundaries. Never silently rewrite digits, units, or hyphens."""
    return '\n'.join(line.rstrip() for line in text.replace('\r\n', '\n').split('\n')).strip()

def page_chunks(text: str, limit: int = 600) -> list[str]:
    """Character-bounded slices, without overlap, from exactly one page."""
    if limit < 1:
        raise ValueError('limit must be positive')
    # This deliberately simple splitter preserves every character in order.
    # Production systems should prefer reviewed section/table boundaries.
    return [text[i:i + limit] for i in range(0, len(text), limit)]

def ocr_page(path: Path, number: int) -> str:
    with tempfile.TemporaryDirectory(prefix='pdf-evidence-') as directory:
        prefix = Path(directory) / 'page'
        subprocess.run(['pdftoppm', '-f', str(number), '-l', str(number),
                        '-singlefile', '-r', '180', '-png', str(path), str(prefix)],
                       check=True, timeout=60, capture_output=True)
        result = subprocess.run(['tesseract', str(prefix) + '.png', 'stdout',
                                 '-l', 'eng', '--psm', '3'], check=True,
                                timeout=60, capture_output=True, text=True)
        return normalize(result.stdout)

def extract(path: Path, allow_ocr: bool = False, limit: int = 600) -> dict:
    # Validate before iterating so even a zero-page document rejects bad limits.
    if limit < 1:
        raise ValueError('limit must be positive')
    path = path.resolve(strict=True)
    if path.stat().st_size > MAX_BYTES:
        raise ValueError('file exceeds this demonstration byte limit')
    digest = hashlib.sha256(path.read_bytes()).hexdigest()
    reader = PdfReader(path)
    if reader.is_encrypted:
        raise ValueError('encrypted PDFs need a separate authorized workflow')
    if len(reader.pages) > MAX_PAGES:
        raise ValueError('file exceeds this demonstration page limit')
    pages, chunks = [], []
    for number, page in enumerate(reader.pages, start=1):
        native = normalize(page.extract_text() or '')
        # Routing hint, NOT a completeness or correctness check.
        sparse = len(re.findall(r'[A-Za-z]', native)) < 40
        if sparse and allow_ocr:
            text, method = ocr_page(path, number), 'ocr'
            status = 'review_required' if text else 'empty_after_ocr'
        else:
            text, method = native, 'native'
            status = 'needs_ocr_or_review' if sparse else 'review_required'
        page_id = f'{digest}:p{number}'
        pages.append({'page_id': page_id, 'page': number, 'method': method,
                      'status': status, 'text': text})
        for index, part in enumerate(page_chunks(text, limit), start=1):
            chunks.append({'chunk_id': f'{page_id}:c{index}', 'page_id': page_id,
                           'page': number, 'method': method, 'text': part})
    return {'document_sha256': digest, 'page_count': len(pages),
            'character_limit': limit, 'pages': pages, 'chunks': chunks}

if __name__ == '__main__':
    parser = argparse.ArgumentParser()
    parser.add_argument('pdf', type=Path)
    parser.add_argument('--ocr', action='store_true')
    parser.add_argument('--limit', type=int, default=600)
    args = parser.parse_args()
    print(json.dumps(extract(args.pdf, args.ocr, args.limit), indent=2))
Download the fictional three-page handbook PDF to reproduce the input. It contains no real operating instructions or personal data. The recorded environment used Python 3.12.14, pypdf 6.10.0, Poppler 26.05.0, and Tesseract 5.5.0 with English language data. Different parser or OCR versions may produce different spacing or recognition results.
Save the code as pipeline.py. A native-only run is python pipeline.py synthetic-handbook.pdf; an OCR-enabled run adds --ocr. The default chunk limit is 600 characters. The output includes the full hash in its identifiers, which is convenient for an auditable local example but verbose for a prompt. A production application can use shorter opaque IDs backed by a collision-safe mapping, provided the source relationship remains durable and access-controlled.
In the recorded run, native extraction produced page-text lengths of 650, 533, and zero characters. OCR changed the third page to 302 characters, with its method recorded as ocr. At the 600-character limit, the native-only output contained three chunks and the OCR-enabled output contained four. These counts describe this exact fixture and configuration. They are not throughput measurements, quality percentages, or a general estimate of how much content a real page will produce.
The independent suite passed 36 unittest methods, including a fresh local OCR run. The checks compare page identities, reconstruction of each page from its chunks, bounded chunk lengths, and critical fixture text. They also verify the service-limit values and the Saturday conditions against the synthetic source. An independent review exercises boundary and failure cases in addition to the happy path. Importantly, the script does not parse the native table into a trusted relational structure or answer a question. Those are later stages with separate tests, rather than capabilities implied by a successful extraction run.
8. Send a narrow evidence packet to DeepSeek
Once evidence is reviewed, select the portions relevant to a specific question. A request about the Saturday pilot needs its scope and exception, not the entire handbook and every unrelated attachment. Keep source IDs near the text they identify. Tell the model what the question is, what evidence is available, and how to express missing or conflicting information. Avoid asking it to repair undocumented OCR defects by intuition; a plausible correction is still a guess unless checked against the source.
For example, ask: “For lane N7 on Saturday, what cutoff and per-carton mass limit does the supplied handbook state? Cite the supplied evidence ID. If the evidence does not specify a value, say that it is not stated.” The expected fixture answer is 10:00 UTC and 8.0 kg per carton, with physical page 3 cited. A Sunday delivery promise would be unsupported: the source only says Sunday dispatch is closed, and dispatch timing is not delivery timing.
Document text should remain untrusted task data. A paragraph saying “ignore previous instructions” must not become an application instruction merely because OCR recovered it. Keep permissions and tool execution outside the document’s control. Our prompt-injection prevention guide explains that boundary in depth. Here, the practical implication is to carry evidence without granting it authority over the workflow.
If selected text omits a layout-dependent fact, send a verified page image or crop through the documented vision-capable route and retain its source coordinates. Test whether the chosen image representation makes small characters readable; higher-detail settings are not an accuracy guarantee. Minimize the content and metadata leaving your application, and check file-storage choices if you use uploaded images. Our API data-minimization guide covers that outbound review and the distinction among storage boundaries.
9. Validate citations in layers
Start with mechanical checks. Does every returned evidence identifier exist in the packet supplied to this request? Does its page belong to the stated document revision? If the answer includes a quote, does that quote occur in the corresponding stored extraction under the normalization rules you actually use? Reject invented IDs and impossible page numbers before presenting a polished answer. These checks are inexpensive compared with diagnosing a convincing but untraceable explanation after a user acts on it.
Then check support. A real identifier does not mean the cited text entails the claim. Page 3 might support a Saturday cutoff while saying nothing about delivery time. Page 1 might state a general rule that is overridden for the specified lane. An answer can quote accurately and still combine conditions incorrectly. Validate critical values and scope against the underlying evidence, and route uncertain or consequential decisions to a reviewer who can open the original page.
Finally, recognize that the extraction itself can be wrong. Exact quote matching only shows that the model repeated your transcript; it does not show that the transcript matches the PDF. For critical numbers or ambiguous OCR, compare the original image, the extracted characters, and the resulting claim. This is why provenance matters: it makes correction possible. It is not a substitute for correction or a certificate of truth.
Use structured output to make the contract easier to validate, but keep structural validity separate from evidential validity. A JSON object with a correctly typed mass value can still contain the wrong number or unit. Our structured-output guide covers parsing and validation mechanics. The document-specific addition is a requirement that each accepted field retain its scope, source location, and review status, rather than being detached into a clean-looking record too early.
10. Evaluate the ingestion layer on its own
Build a small gold set from the document families your application is permitted to process. Include clean digital prose, image-only pages, mixed pages with small digital headers, existing OCR errors, multiple columns, and tables that continue across pages. Add blank pages, unfamiliar languages, rotated scans, and files that should be rejected or reviewed. A collection containing only easy first pages will reward a pipeline that fails exactly where exceptions tend to live.
Annotate required content blocks, their source pages, reading order, critical values, units, table associations, and expected omissions. Coverage should count required blocks, not just extracted characters. A page can yield thousands of characters while losing one decisive footnote. Character or word error rates are useful for sampled transcriptions, but pair them with exact checks on high-consequence fields. A global score can hide a single altered decimal that matters more than many harmless spacing differences.
Measure table structure separately from text recognition. Ask whether every value retains the correct row, column, header, unit, and note. For reading order, test whether a person can follow the reconstructed argument without jumping between columns or attaching a footnote to the wrong sentence. Public parsing benchmarks such as OmniDocBench illustrate why text, tables, formulas, and order deserve separate attention. Their published results do not substitute for testing your own input distribution, and no benchmark run is claimed here.
After ingestion passes its gates, evaluate retrieval and answers. Include unanswerable questions, conflicting revisions, and questions that require an exception rather than the general rule. Track valid citations and supported answers separately, along with review frequency and per-stage latency. Our RAG evaluation guide addresses the downstream system. Keeping these measurements separate helps you repair a missing page instead of spending time tuning a prompt that never received it.
11. Diagnose failures at the earliest broken stage
When an answer is wrong, reconstruct its path backward. First inspect the cited source and revision, then the evidence packet, then the chunk, then the page extraction, and finally the original page. If the fact never entered the transcript, change extraction or OCR. If it was extracted but separated from its exception, change representation or chunking. If the correct evidence reached the model but the answer misapplied it, investigate the task instruction and answer validator.
Keep operational errors visible. An OCR timeout should produce an explicit unresolved page, not an empty string that resembles a blank sheet. The teaching script fails fast on parser or OCR errors and does not emit a partial manifest; a production wrapper should catch these failures and persist an explicit unresolved page status. A parser exception should not erase the document from quality metrics. Cache derived results under the source hash and processing configuration so a parser or language-pack change cannot silently reuse stale text. Store enough diagnostic information to reproduce a failure while avoiding unnecessary document content in ordinary application logs.
A useful release unit includes the parser version, OCR settings, normalization rules, chunking logic, evidence schema, and answer checks. Re-run the relevant fixtures when any part changes. A library update that improves one layout may change whitespace, coordinates, or reading order in another. Compare the evidence representation before celebrating an improved final answer score, and retain a rollback path for the complete configuration rather than only the model name.
The practical goal is an honest document system: it knows which pages it processed, which relationships it preserved, and which claims still require inspection. DeepSeek can interpret the evidence you provide, but your application decides whether that evidence is complete enough to support the task. Preserve the source, expose uncertainty early, and make every important answer easy to check against the original page. That discipline is more valuable than a larger context window filled with an unreliable transcript.
Sources & References
Primary documentation checked October 3, 2026. The local fixture and extraction checks described above are separate from the vendors’ documentation and from any published benchmark.
- DeepSeek: current models and capability table
- DeepSeek: vision inputs and image processing
- DeepSeek: Files API supported formats and storage settings
- pypdf: text extraction capabilities and limitations
- pypdf: PDF page labels
- PyMuPDF: reading order, positional text, and tables
- OCRmyPDF: processing modes and their effects
- OCRmyPDF: sidecars, languages, and page selection
- Tesseract: image quality, segmentation, and table limitations
- DeepSeek-OCR: official repository
- DeepSeek-OCR-2: official repository
- OmniDocBench: document-parsing evaluation project
